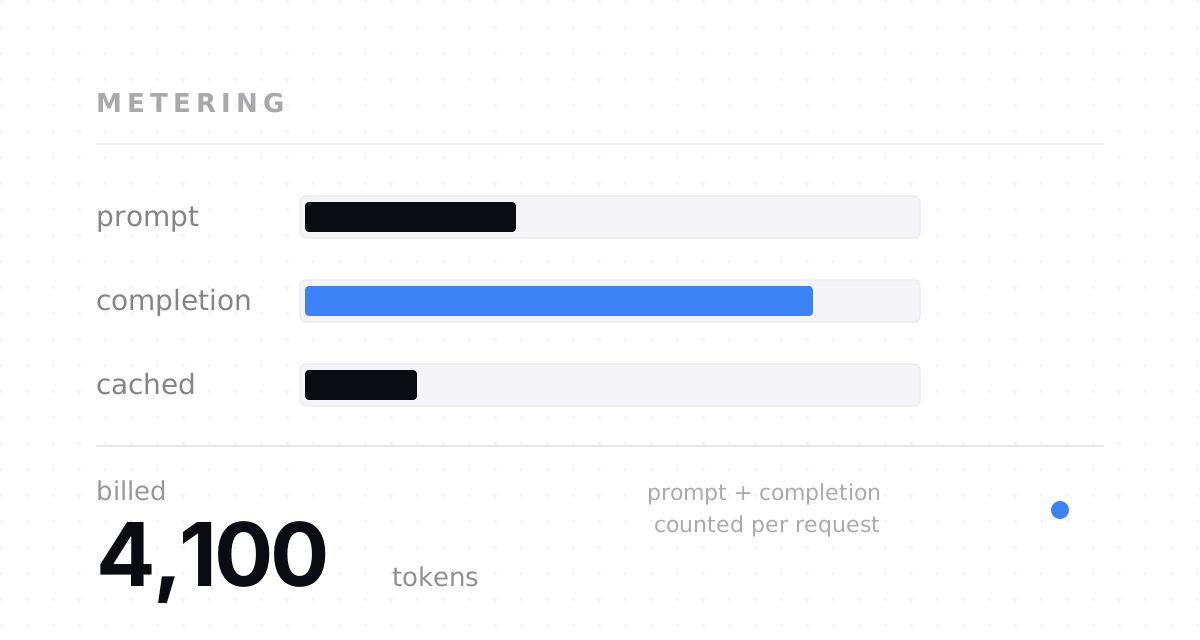
A request that looks cheap can cost more than expected once the completion length is unbounded. Hisoka records prompt tokens and completion tokens separately for every call.
Open the request log and you get latency, both token counts, and the upstream status. That is enough to answer "which model is actually cheaper for this workload" with numbers instead of guesses.